Services / Generative AI and RAG
Generative AI grounded in your knowledge
Assistants and search that answer from your own documents and data, with sources your people can check.
Overview
Answers your people can check
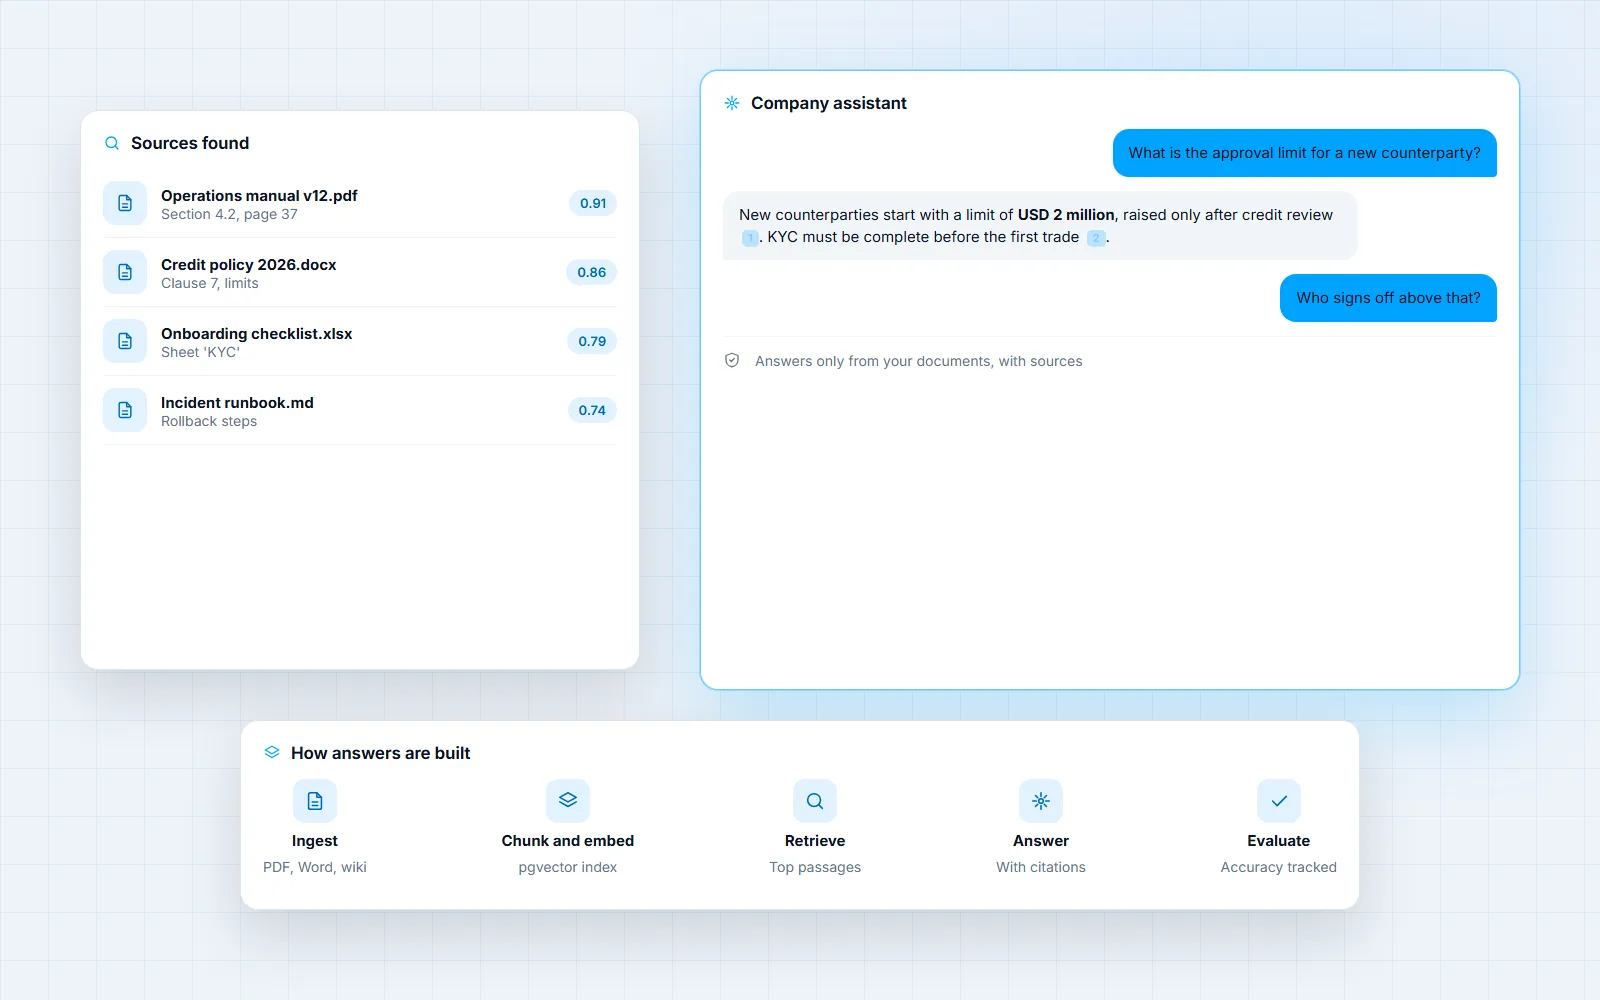
Generative AI is only useful at work when its answers are grounded in your own knowledge: policies, contracts, product documentation, tickets and data. Retrieval-augmented generation (RAG) gives the model the right sources at the moment it answers.
We build the whole chain: ingesting and cleaning content, embeddings and search with pgvector, prompts that cite their sources, and the access rules that make sure people only see what they are allowed to see.
The challenge
Where teams get stuck
- Answers without sourcesPeople cannot rely on an answer they cannot verify.
- Sensitive data in public toolsStaff paste confidential text into consumer chatbots because there is no safe alternative.
- Knowledge spread everywhereAnswers sit in documents, wikis, tickets and inboxes nobody can search together.
Capabilities
What we deliver
Retrieval pipelines
Search over documents, tickets and databases with embeddings and pgvector.
Assistants and copilots
Chat and in-app assistants for staff and customers.
Data protection
PII redaction, access control and private hosting.
Prompt and quality management
Versioned prompts, evaluation sets and guardrails.
Our approach
How we deliver it
01
Find the questions
Start from the questions people ask most and the sources that answer them.
02
Prepare the knowledge
Clean, split and index documents, carrying permissions across.
03
Build the assistant
Retrieval, prompts and citations tuned against real questions.
04
Roll out and measure
Track usage, answer quality and gaps, and keep improving.
Technology
What we build with
RAG, embeddings and LLM gateways are part of how we build AI, including in our own pricing platform. See the AI Spot Price Recommendation Engine
Outcomes
What you get
Faster answers
Staff find answers in seconds instead of searching for hours.
Answers people trust
Every answer shows where it came from.
Safe by design
Data stays in your environment, with personal data redacted.
Questions we hear
Frequently asked questions
Can it run in our own cloud?
Yes. We deploy on Azure AI Foundry, AWS or self-hosted models, so your data stays in your environment.
Will it make things up?
Answers are grounded in retrieved sources with citations and tested against evaluation sets. When the sources do not answer, the assistant says so.
What data do we need to start?
The documents your team already searches every day are usually enough for a first assistant.
Can it answer from databases, not only documents?
Yes. Assistants can combine document search with read-only queries against approved data sources.
Let’s talk
Have a project in mind?
Tell us what you are trying to achieve. The first conversation is free, you will leave it with practical next steps, and we reply to every enquiry within 4 hours.