Services / DevOps and observability
Faster, safer releases
CI/CD, Kubernetes and observability that let teams ship often and find problems before customers do.
Overview
Ship often, sleep well
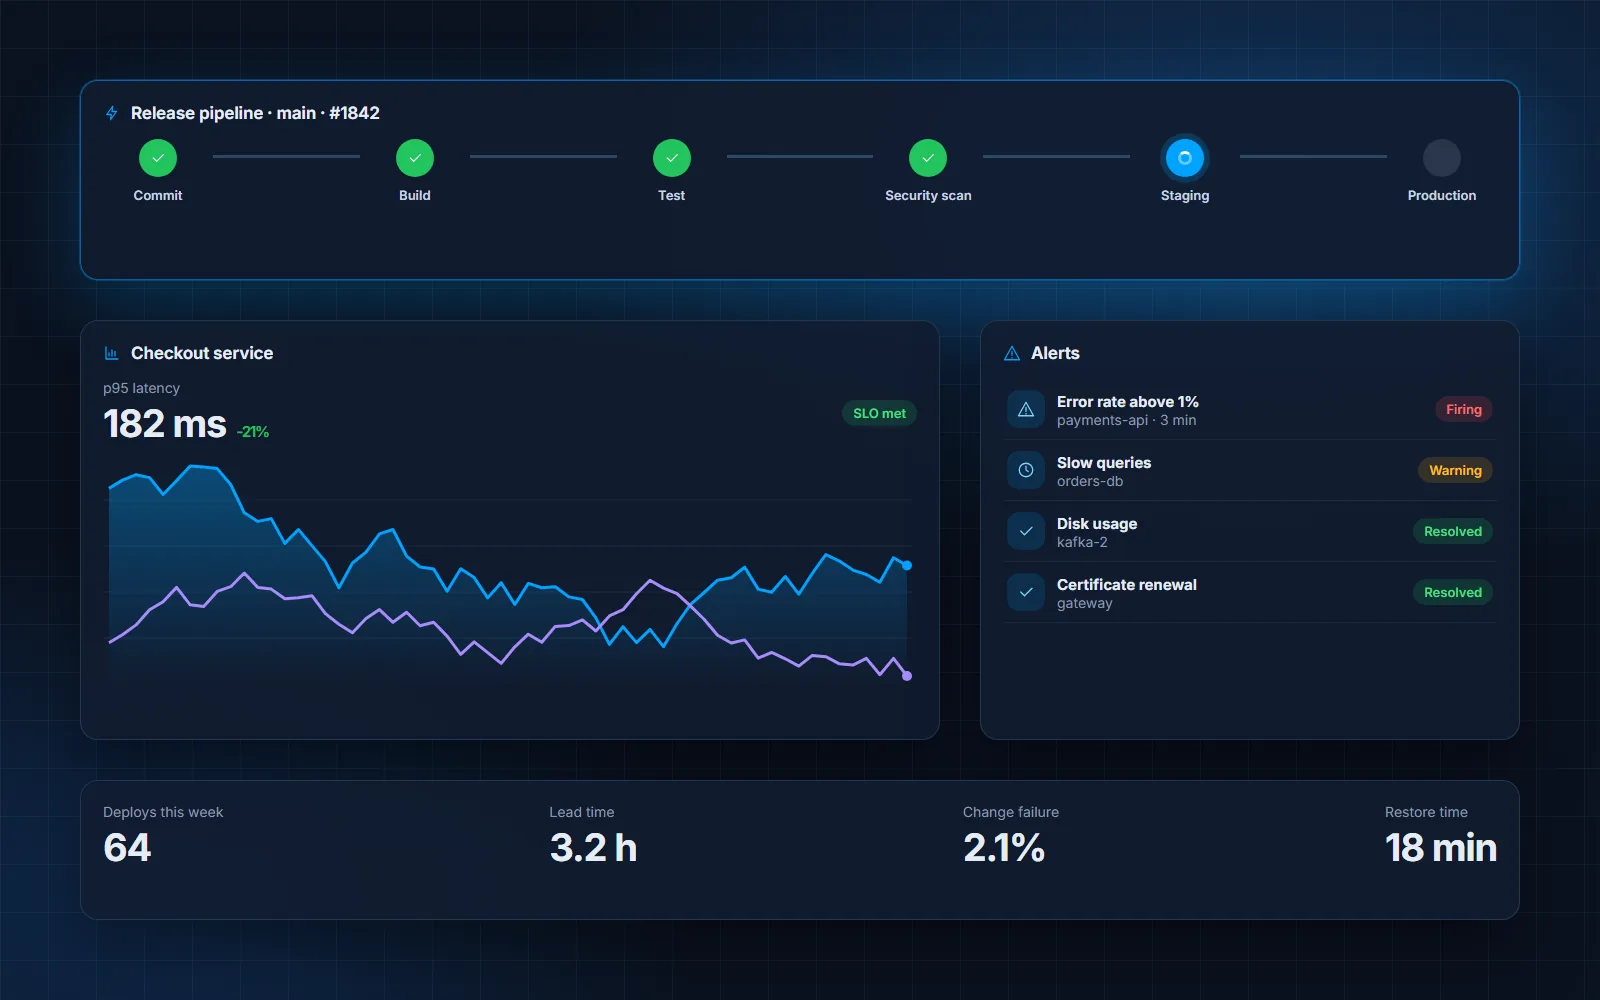
Fast, reliable delivery depends on the path from commit to production. When builds are slow, environments drift and problems are found by customers, teams slow down and releases become events to fear.
We build pipelines and platforms that make the right way the easy way: automated builds, tests and deployments, Kubernetes templates teams can reuse, and observability that shows what every service is doing, with alerts that reach the right person before customers notice.
The challenge
Where teams get stuck
- Slow, manual releasesDeployments need a checklist, a weekend and a lot of luck.
- Problems found by customersWithout good monitoring, outages surface through complaints.
- Drifting environmentsTest and production differ, so bugs appear only after release.
Capabilities
What we deliver
CI/CD pipelines
GitHub Actions, Azure DevOps and Jenkins, automated end to end.
Kubernetes platforms
Reusable deployment templates teams can adopt.
Observability
Grafana, Prometheus, Datadog and ELK: metrics, logs and traces.
DevSecOps
Security checks built into every pipeline.
Our approach
How we deliver it
01
Measure
Baseline lead time, deployment frequency, failure rate and recovery time.
02
Automate
CI/CD with tests, security checks and repeatable deployments.
03
Observe
Metrics, logs, traces and alerts for every service.
04
Improve
Regular reviews of incidents and pipeline speed.
Technology
What we build with
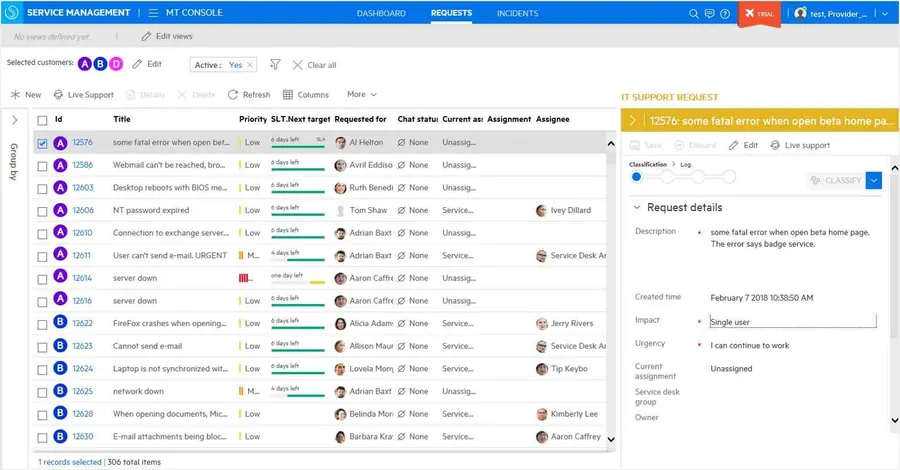
Reusable Kubernetes templates and faster CI/CD, adopted across engineering teams. See the OpenText SMAX case study
Outcomes
What you get
Faster delivery
Shorter builds and smaller, more frequent releases.
Fewer incidents
Issues spotted and fixed before customers notice.
Consistent environments
Infrastructure defined as code.
Case studies
Related case study
Our accelerator
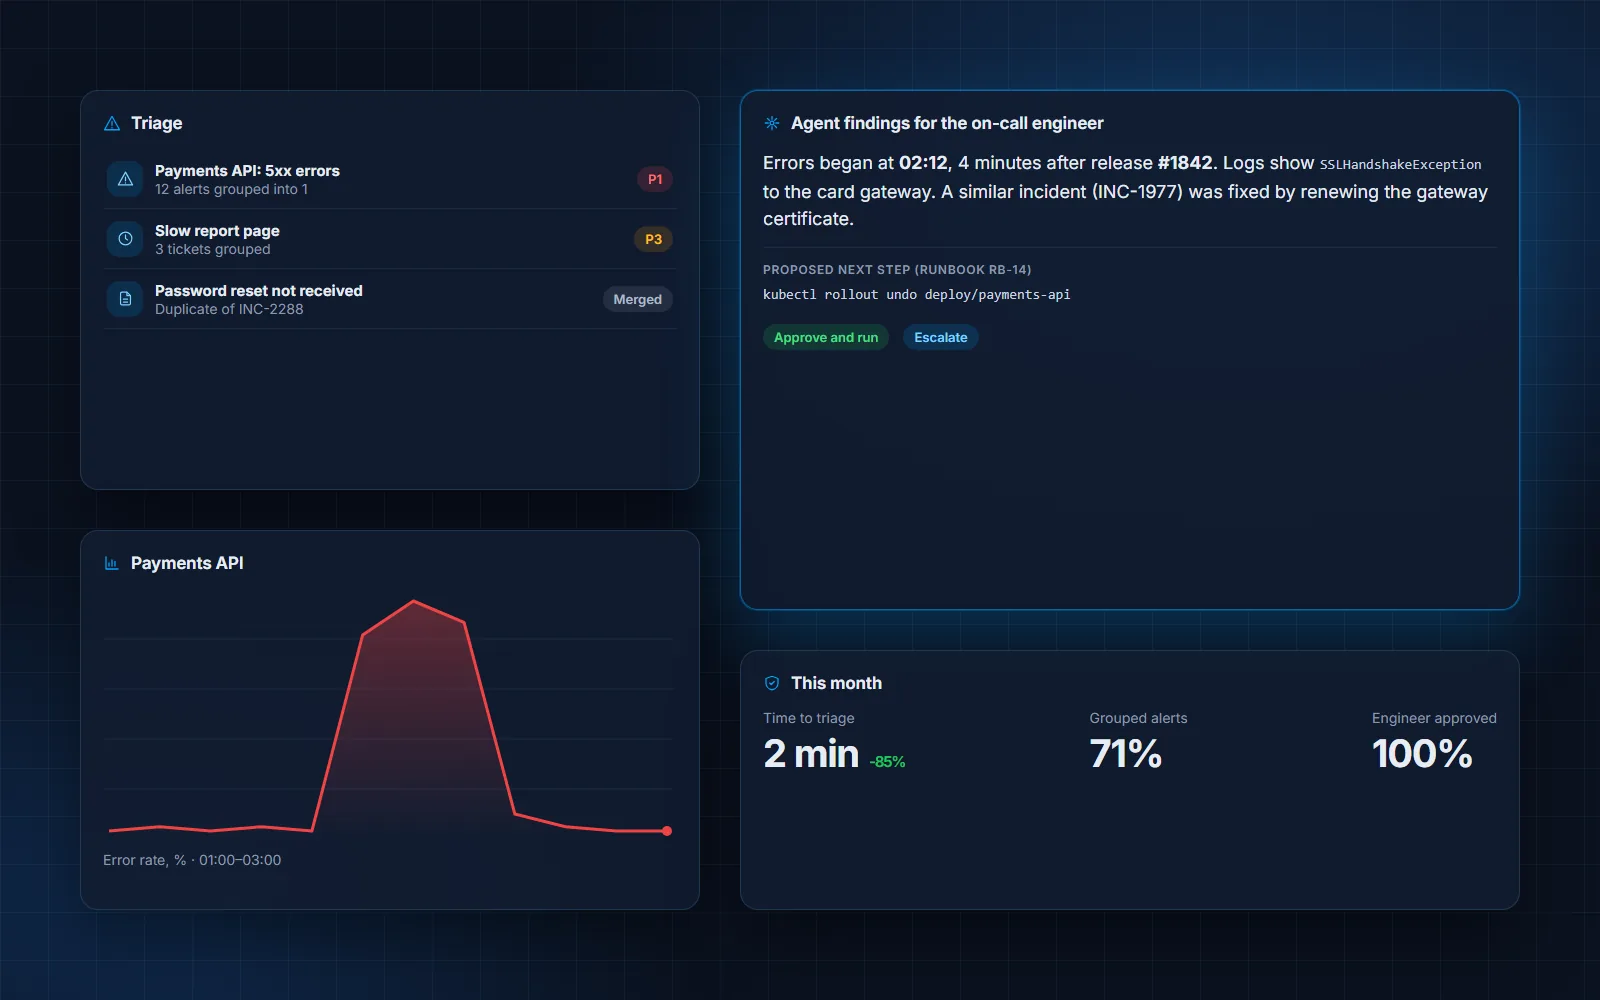
Support Operations Agent
An AI agent that triages alerts and tickets, gathers logs and runbook steps, and proposes a fix for the on-call engineer to approve.
Questions we hear
Frequently asked questions
Can you work with our current tools?
Yes. We improve what you have before suggesting anything new.
How do you measure improvement?
Deployment frequency, lead time, failure rate and time to recover, tracked from the start.
Do you train our team?
Yes. Pairing and documentation are part of every engagement.
Can you migrate our pipelines to a new tool?
Yes, for example from Azure DevOps to GitHub Actions, running both side by side until the new pipelines are proven.
Let’s talk
Have a project in mind?
Tell us what you are trying to achieve. The first conversation is free, you will leave it with practical next steps, and we reply to every enquiry within 4 hours.